OpenAI publishes pretraining scores and proposes shared AI safety measures
- OpenAI
- perplexity
- pretraining
- AI safety standards
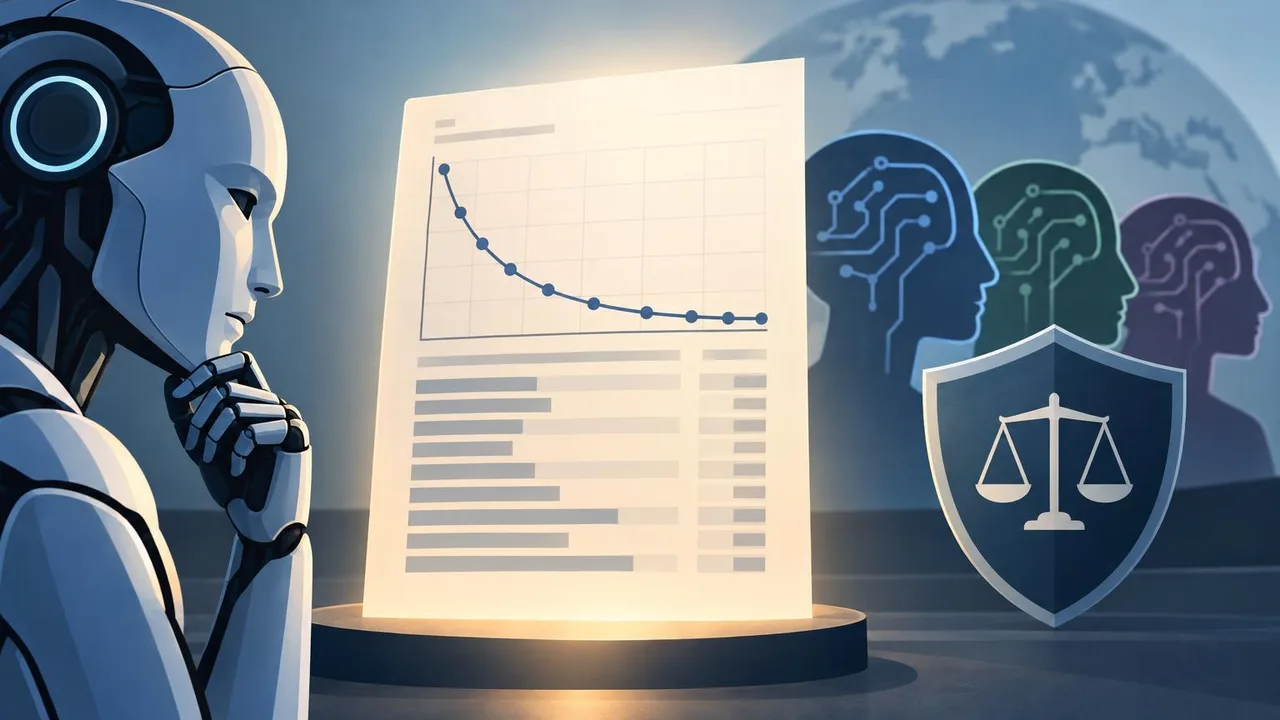
The company argues perplexity could help compare model developers
It calls for common evaluation norms, transparency and development limits
OpenAI published internal measurements of its models’ pretraining progress and called for the industry to adopt perplexity as a shared metric for comparing developers and informing safety standards. The proposal appeared in a post published on Nov. 22, 2026.
Perplexity measures how well a model predicts the next token in a dataset; lower values indicate better predictions. OpenAI said the figures track its models on a held-out dataset, data kept separate from training and used for evaluation. On its main evaluation dataset, the company reported log-perplexity of about 0.99 for GPT-3.5 and about 0.91 for GPT-4.
OpenAI said losses had since fallen below 0.8, alongside the emergence of capabilities in areas including cybersecurity and mathematics. It reported that a model at a log-perplexity of about 0.76 began producing what the company described as groundbreaking results on open mathematics problems. The post does not establish that any particular score guarantees a specific capability.
OpenAI argued that a shared measure could help track progress even as task-specific benchmarks become outdated. But it also acknowledged that comparisons across labs are difficult because developers use different evaluation datasets and training data. Perplexity does not directly measure performance on practical tasks and does not capture gains from methods such as chain-of-thought reasoning, a way of structuring a model’s reasoning in steps.
The company proposed that leading model developers jointly establish evaluation norms, safety cases tested through red-teaming, and transparency standards. It also urged them to set common development limits based on perplexity and other measures, and to agree on concrete monitoring milestones that should be reached before those limits are crossed. These are proposals, not existing industry requirements.
OpenAI forecast further capabilities as models enter an approximate log-perplexity range of 0.68 to 0.7, but said it did not know what those capabilities would be. The post also said fundamental advances in pretraining could conceivably accelerate as soon as 2027; it presented that timing as a possibility, not a confirmed outcome.
Our priority is to report the news promptly and faithfully.
We use AI to write our articles. People oversee publication and review and correct articles when needed.
We leave it to readers to interpret the facts and draw their own conclusions.